Baseten Alternatives in 2026: 6 Inference Platforms Compared on Features
We compared 6 Baseten alternatives on how you deploy, scale-to-zero and cold starts, fine-tuning, compliance and self-hosting, verified in each provider's docs on Nov 17, 2026.
The best Baseten alternatives in November 2026 depend on how your team ships models, not just on GPU price. Modal suits Python teams that want code-defined infrastructure. Fireworks AI and Together AI suit LLM teams that want per-token APIs, fine-tuning and dedicated GPUs in one place. RunPod Serverless suits container-first teams, and Replicate suits teams packaging models with Cog. We checked each feature in the provider's own docs on November 17, 2026.
Last verified: November 17, 2026. Features and prices come from each provider's public docs and pricing pages.
TL;DR
- Closest all-round match to Baseten: Fireworks AI, with dedicated GPUs, fine-tuning, SOC 2 Type II, HIPAA and bring-your-own-cloud.
- Best for Python teams: Modal, where infrastructure is defined in code and GPU memory snapshots target cold starts.
- Best for any container: RunPod Serverless, with GitHub auto-release and pre-warmed active workers.
- Best for packaging custom models: Replicate, built around the open-source Cog tool and now part of Cloudflare.
- Lowest H100 list price: Koyeb at $2.50/hr, but Mistral acquired it and new users need a paid plan.
What does Baseten offer?
Baseten sells 5 products: Dedicated Inference, Model APIs, Training, Sandboxes and Grid, a control layer for model access and routing (Baseten). You define a model with a config.yaml, a Python model class or a custom Docker server. Multi-step pipelines run as one deployment with Chains (Baseten docs).
Baseten maintains its own engines: Engine-Builder-LLM (TensorRT-LLM), BIS-LLM for mixture-of-experts models and BEI for embeddings. vLLM and SGLang run in a custom Docker container. Its open-source serving library, Truss, is MIT-licensed (GitHub).
On security, Baseten states SOC 2 Type II and HIPAA support with a BAA. It also offers single-tenant and self-hosted deployments (Baseten security). Deployments scale to zero by default, and replica start-up is billable.
How do Baseten alternatives compare on features?
| Platform | How you deploy | Scale to zero and cold starts | Fine-tuning | Compliance stated | Isolation or self-host | H100 $/hr |
|---|---|---|---|---|---|---|
| Baseten | config.yaml, Python class or Docker; Chains for pipelines | Default min_replica: 0 | Yes (Training, Loops SDK) | SOC 2 Type II, HIPAA with BAA | Single-tenant, self-hosted | $6.50 |
| Fireworks AI | Model library, uploaded models (supported architectures), LoRA add-ons | After 1 hour idle by default | Yes, incl. reinforcement fine-tuning | SOC 2 Type II, HIPAA | Bring your own cloud | $8.00 |
| Together AI | Hosted, fine-tuned or uploaded models; containers for custom models | Replicas autoscale; stop manually | Managed SFT and DPO | SOC 2 Type 2 | Not stated on pages checked | $5.49 |
| Modal | Python SDK: functions with @app.function(gpu=...) | Idles at zero; memory snapshots | Run your own training code | SOC 2 Type II, HIPAA ready | Region pinning (price multiplier) | ~$3.95 |
| RunPod Serverless | Any Docker container; GitHub auto-release | Flex workers scale to zero; FlashBoot | Not stated for Serverless | SOC 2 Type II, SOC 3, ISO 27001, HIPAA, GDPR | Secure Cloud network isolation | $5.89 |
| Replicate | Cog (cog.yaml + run.py) or public models | Deployments scale to zero; min/max instances | Trainings API | Not stated on pages checked | Private models on dedicated hardware | $5.49 |
| Koyeb | Git push, Docker or CLI | Scales to zero; sub-200 ms cold-start claim | Not stated | Not named on koyeb.com | Not stated | $2.50 |
H100 prices are single-GPU list prices, checked November 17, 2026. Modal's is converted from $0.001097/sec. For raw GPU rental floors, see our cheapest GPU page.
Notes on each alternative
Fireworks AI: the closest all-round match
Fireworks deploys models from its library or uploads your own, for supported architectures. It supports LoRA add-ons and pre-validated "deployment shapes" tuned for speed, throughput or cost (Fireworks docs). It offers FP8 quantization, which it says cuts cost 30–50%, plus speculative decoding. GPUs include NVIDIA A100 through B300 and AMD MI325X and MI350X.
Fireworks says it is SOC 2 Type II and HIPAA certified (Fireworks FAQ). Fine-tuned models can deploy to bring-your-own-cloud, serverless, on-demand or reserved capacity (Fireworks blog). The tradeoff: its H100 list price is higher than Baseten's.
Together AI: open models plus GPU clusters
Together runs serverless open models, dedicated endpoints, fine-tuning, GPU clusters and code sandboxes (Together AI). Dedicated endpoints serve Together-hosted models, models fine-tuned on Together or fine-tunes you upload. They use the same API as serverless, so you can prototype per-token and move to dedicated without code changes (Together docs). Together completed a SOC 2 Type 2 examination in 2025 (Together blog).
Modal: infrastructure as Python code
On Modal, you mark Python functions with decorators and pick a GPU with gpu=. Memory snapshots skip start-up work such as imports; Modal reports 3–10x faster starts for initialization-heavy functions. GPU memory snapshots are in alpha and don't speed up loading weights from storage (Modal docs). Modal says it is SOC 2 Type II compliant and HIPAA ready (Modal). Pinning a region costs 1.15x to 1.75x base pricing (Modal docs).
RunPod Serverless: bring any container
RunPod deploys any container and can auto-release from GitHub, with rollbacks. It claims sub-200 ms cold starts with FlashBoot, and active workers stay pre-warmed (RunPod). RunPod holds SOC 2 Type 2, SOC 3 and ISO/IEC 27001:2022, with HIPAA and GDPR programs (RunPod Trust Center). Its Secure Cloud adds network isolation for stricter compliance needs.
Replicate: Cog packaging and a public model library
Replicate's open-source Cog builds a Docker image from a cog.yaml and a typed run.py. It generates an HTTP API automatically, and the image also runs on your own servers (Cog). Deployments scale from zero to hundreds of instances, with optional minimums to avoid cold starts (Replicate docs). Cloudflare acquired Replicate, and Replicate says its API is unchanged.
Koyeb: simple deploys, uncertain roadmap
Koyeb deploys code, containers or models with a Git push or CLI call. It claims sub-200 ms cold starts and scales to zero in seconds (Koyeb). It has the lowest H100 list price here. But Mistral AI acquired Koyeb in February 2026 to fold it into Mistral Compute. New users can only register for paid plans (Trending Topics). See Koyeb's provider page.
How do I choose a Baseten alternative?
- You need compliance and fine-tuning in one vendor: Fireworks AI or Together AI.
- You need self-hosting in your own cloud: Baseten or Fireworks (bring your own cloud).
- Your team writes Python and wants fast iteration: Modal.
- You already ship Docker images: RunPod Serverless.
- You want a portable package format: Replicate's Cog.
- You want the lowest list price and accept roadmap risk: Koyeb.
- Steady 24/7 traffic and an in-house team to run vLLM: a raw GPU from our leaderboard. Our spot vs on-demand guide covers interruptible options.
What should you check before switching?
- Billing for idle time: Baseten bills replica start-up, Fireworks waits 1 hour before scaling to zero, and Replicate private models bill all uptime.
- Region costs: Modal charges 1.15–1.75x to pin a region, and Fireworks charges 1.5x for region-restricted deployments.
- Compliance scope: ask for the SOC 2 report and BAA terms. RunPod's controls are strongest on Secure Cloud.
- Ownership changes: Replicate is part of Cloudflare and Koyeb is part of Mistral. Watch both roadmaps.
- Engine support: confirm your model's architecture is supported before you upload it.
- Real cost: run your own numbers in the cost calculator.
Methodology and disclaimers
- Sources: each feature comes from the provider's own docs, linked above. H100 prices come from the Baseten, Fireworks, Together, Modal, RunPod, Replicate and Koyeb pricing pages.
- "Not stated": means we did not find the feature on the provider pages we checked. It may still exist.
- Compliance: we list what providers state publicly. Request the reports before you rely on them.
- Cold-start figures: these are vendor claims. We did not benchmark them.
- Scope: managed inference products only. Order follows how closely each matches Baseten's feature set, not price.
- Accuracy: products change often. Confirm features, prices and regions with the provider before you commit. This is not purchasing advice.
- Accessed: November 17, 2026.
For raw GPU prices by memory tier, see our cheapest cloud GPUs guide.
Frequently asked questions
What is the best alternative to Baseten?+
As of November 17, 2026, Fireworks AI is the closest all-round match. Like Baseten, it offers dedicated GPU deployments, fine-tuning, SOC 2 Type II, HIPAA and a bring-your-own-cloud option. Modal fits Python teams better, and RunPod Serverless fits teams that ship Docker images.
How is Modal different from Baseten?+
On Modal you define infrastructure in Python with decorators like @app.function(gpu=...), and memory snapshots can speed up cold starts. Baseten uses a config.yaml, a Python model class or Docker, and adds single-tenant and self-hosted options. Both state SOC 2 Type II and HIPAA support (checked November 17, 2026).
Which Baseten alternatives support fine-tuning?+
Fireworks AI (including reinforcement fine-tuning), Together AI (managed SFT and DPO) and Replicate (trainings API) offer managed fine-tuning, as of November 17, 2026. On Modal you run your own training code on its GPUs.
Which Baseten alternatives are HIPAA-ready?+
As of November 17, 2026: Fireworks AI says it is SOC 2 Type II and HIPAA certified, Modal says it is HIPAA ready, and RunPod runs HIPAA and GDPR programs with BAAs. Baseten offers HIPAA support with a BAA. Request each provider's reports before you rely on them.
What should I check before switching from Baseten?+
Check idle-time billing (Fireworks waits 1 hour before scaling to zero; Replicate private models bill all uptime), region surcharges (Modal 1.15-1.75x, Fireworks 1.5x), engine support for your model, and ownership changes: Replicate is now part of Cloudflare and Koyeb part of Mistral.
More from the blog
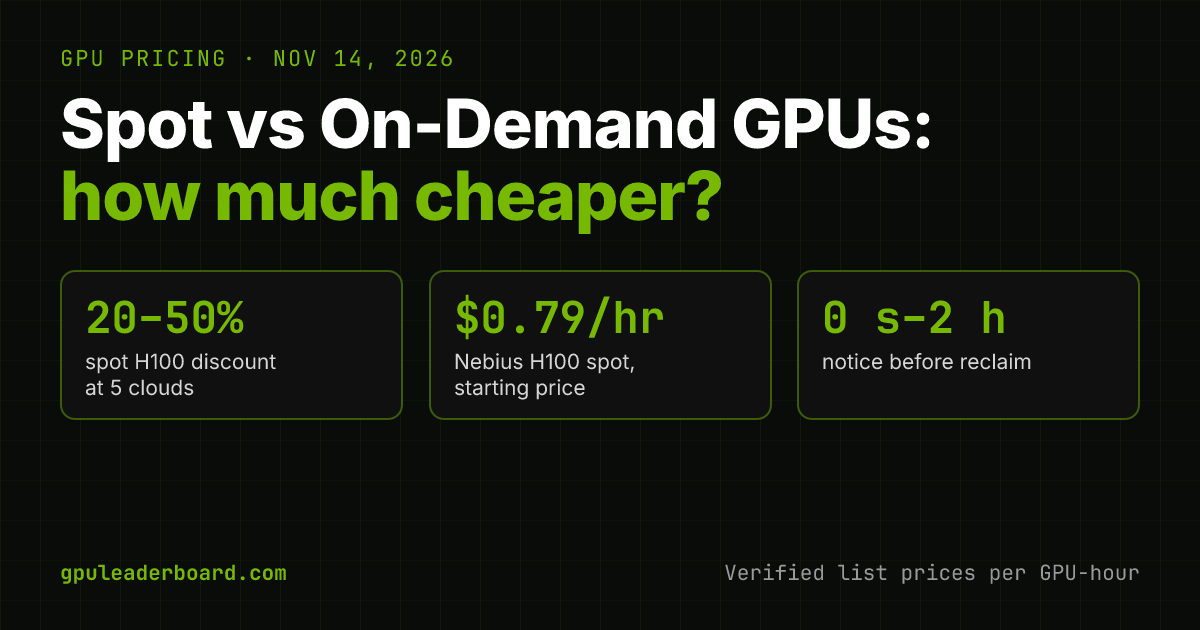
Spot vs On-Demand GPUs: How Much Cheaper, and What You Risk (November 2026)
Spot H100s ran 20% to 50% below on-demand at 5 clouds on Nov 14, 2026, and Nebius preemptible started from $0.79/hr. Here is what each discount costs you in notice, storage and rework.
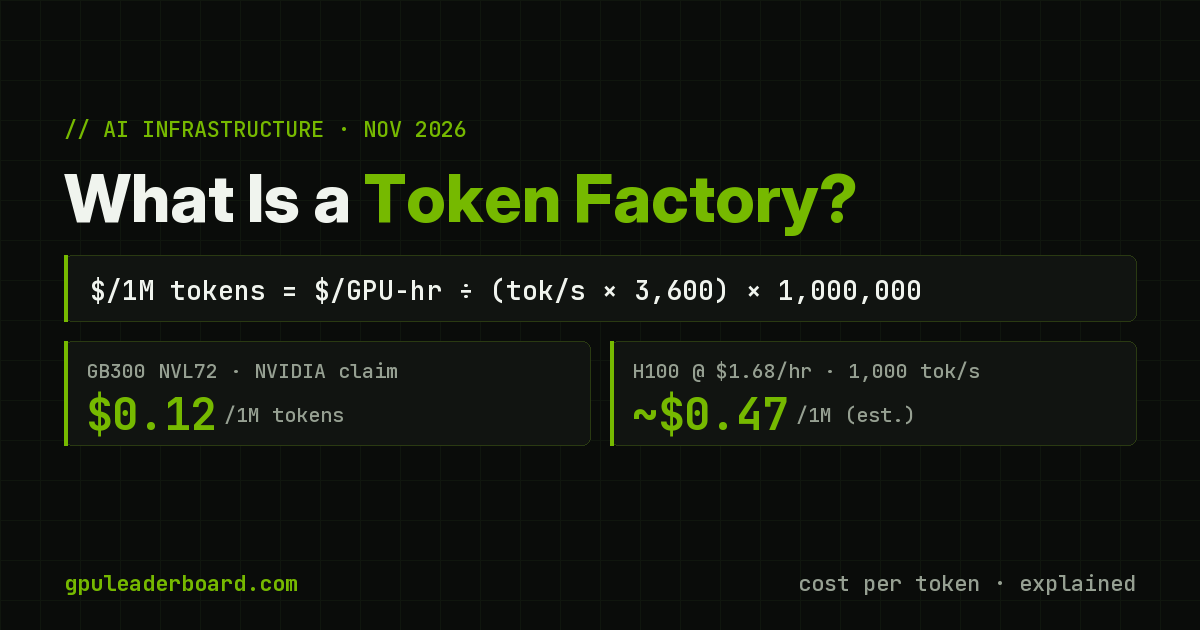
What Is a Token Factory? AI Factory Economics, Explained
A token factory is AI infrastructure judged by one output: tokens. Here is the cost-per-token formula, NVIDIA's Hopper vs Blackwell claim, what tokens cost on GPUs rented at verified Nov 13, 2026 prices, and the 4 products now called "Token Factory."
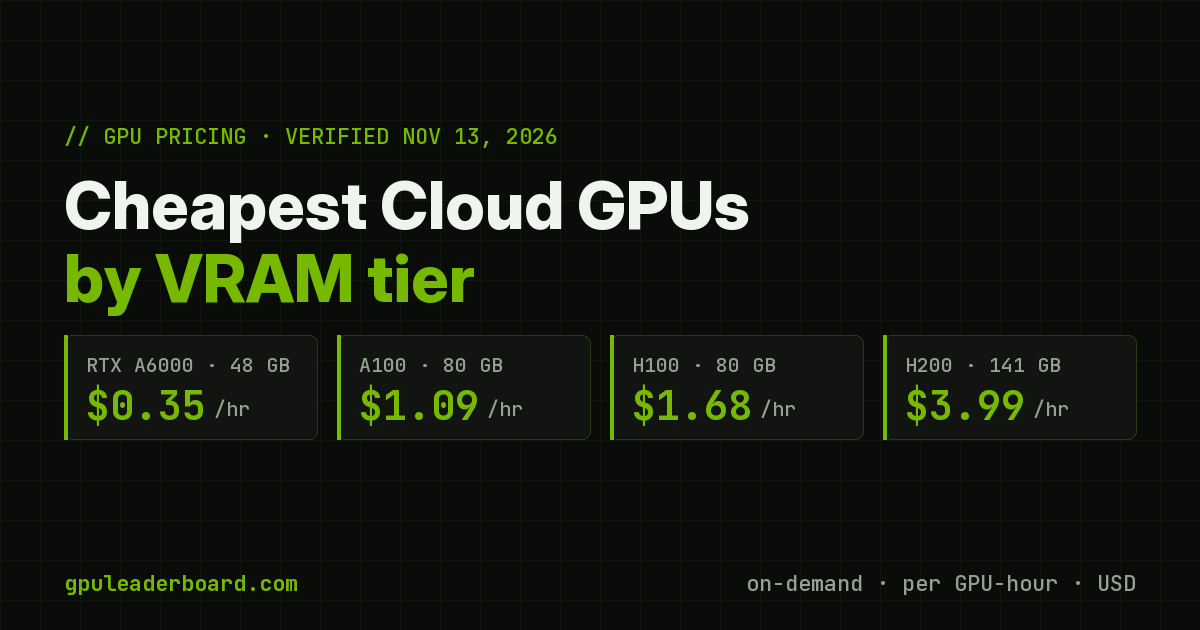
Cheapest Cloud GPUs in November 2026: Verified Prices by VRAM Tier
The cheapest cloud GPU at every VRAM tier on Nov 13, 2026: RTX A6000 at $0.35/hr, A100 80GB at $1.09/hr and H100 at $1.68/hr. Every price is checked on the provider's own pricing page, with interruptible and dedicated options labeled.